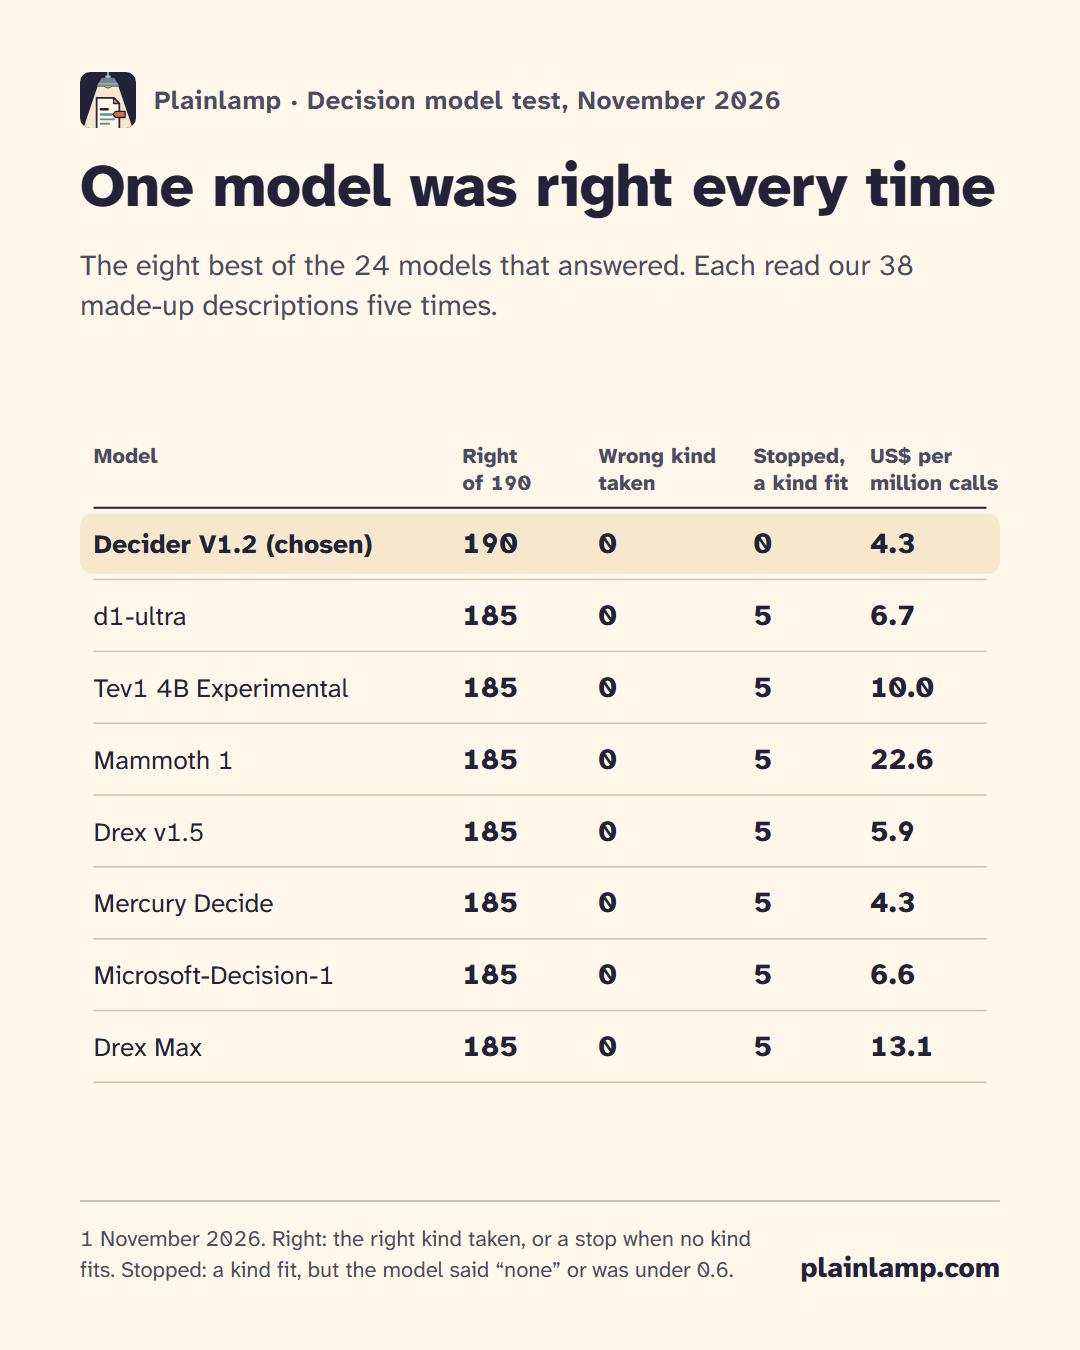
When people describe their document in their own words, a small AI model sorts the words into a kind. We tested 27 of these decision models on 38 made-up descriptions, most of them five times. One was right every time. A car insurance policy split the field. A second test, on 339 new descriptions, put the same model ahead of six of the ten closest models by a gap too big for chance, and no model got more right.
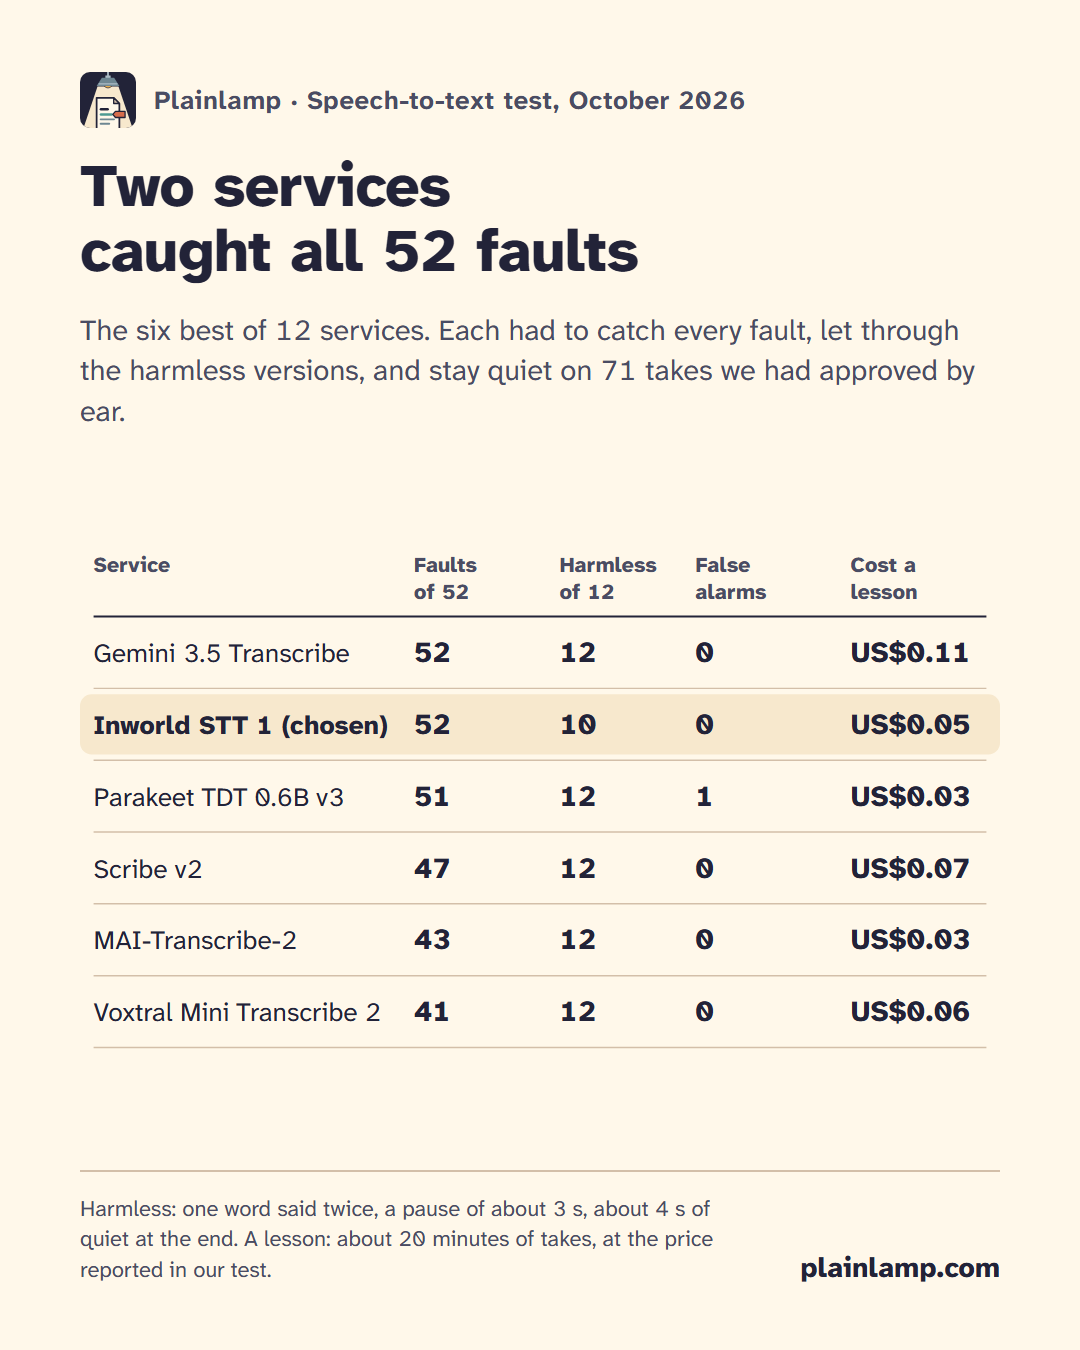
Our AI narrator once repeated 9 seconds of its script, and our pace check passed it. So we tested speech-to-text models on one job: hearing exactly what was said. Only 2 of 15 caught every repeat we planted. What we found, and what we chose.
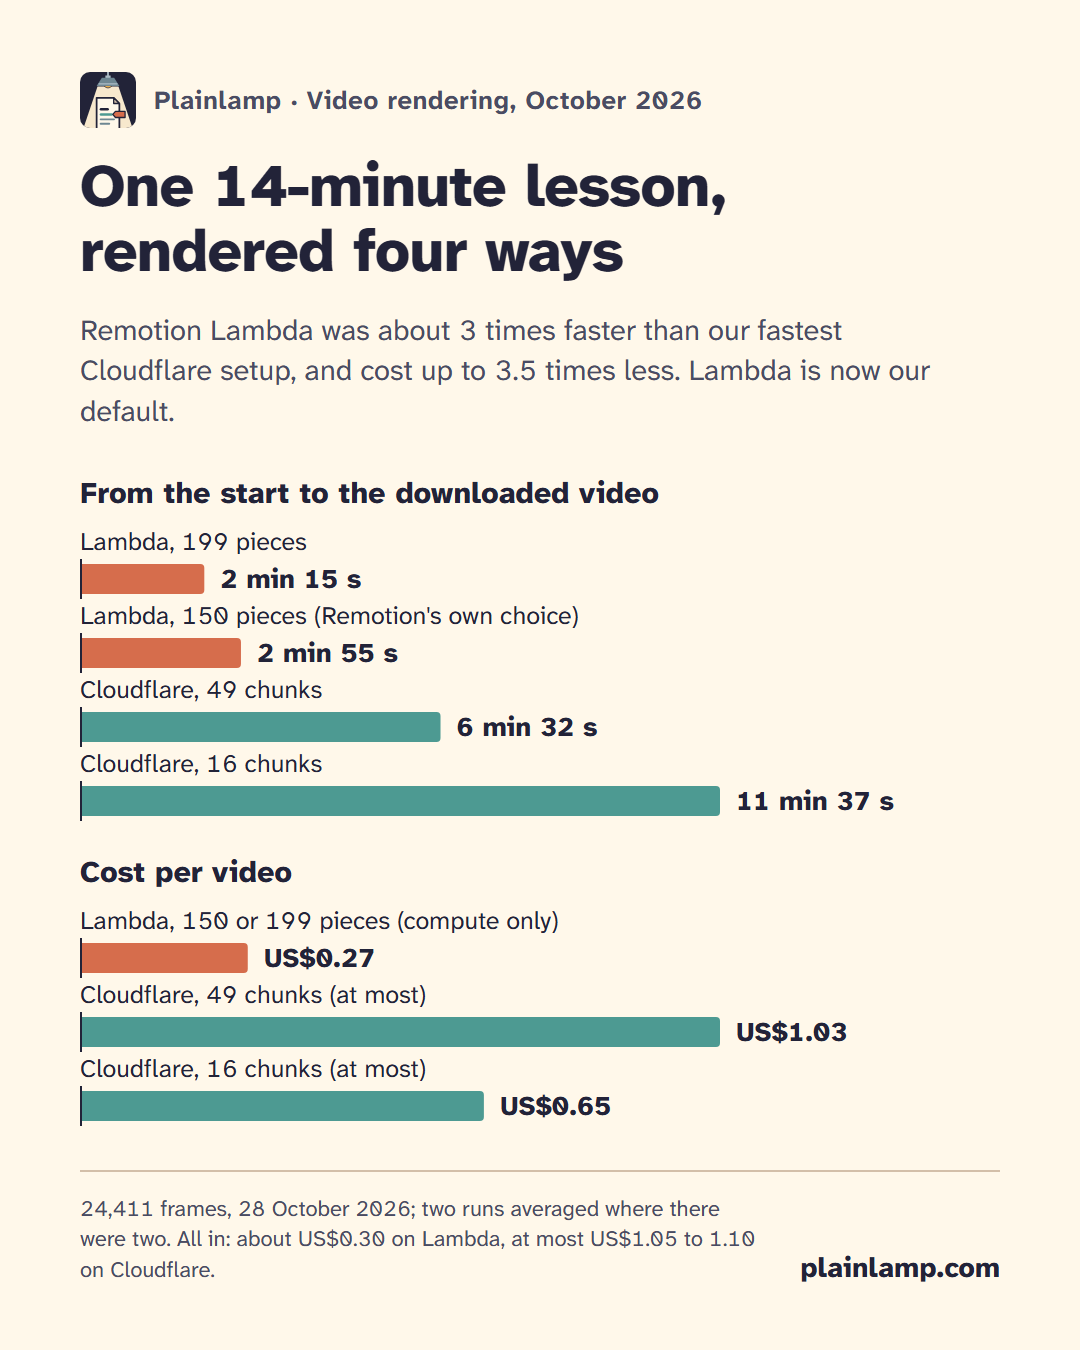
We render our lesson videos with Remotion. We built a fully private route on Cloudflare Containers, timed it against Remotion Lambda on the same 14-minute lesson, and Lambda won on speed and cost. How both work, the numbers, and how we made Lambda's public step small.